By Joy Aliyu
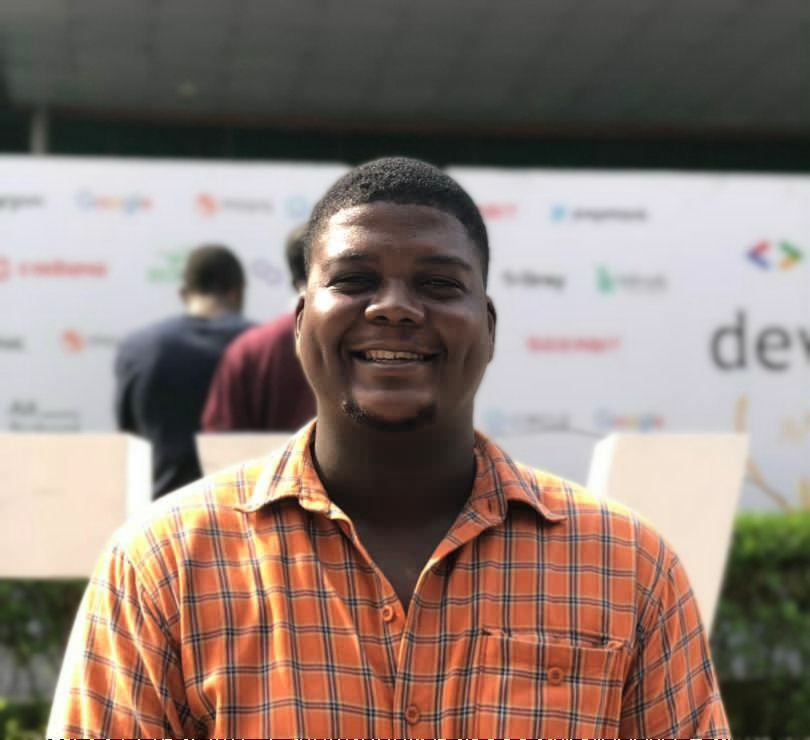
Michael Umeokoli, an Artificial Intelligence, AI, and Software Engineer, in this interview, explains why media literacy alone cannot help individuals spot AI-generated fakes. He also shares insights on how model developers can design systems that make synthetic media traceable, among other issues. Excerpts:
AI-generated content is now everywhere, from realistic deepfake speeches to AI-edited images. Why is labelling this kind of content such an urgent priority?
The speed and volume of AI-generated content are overwhelming. A convincing fake can be made in minutes, a political video, a fabricated breaking-news story, or even a synthetic witness account that never happened. Once it circulates on social media, even the fastest fact-checkers can not undo the initial impression. If we want to keep any level of public trust, model developers need to design systems that mark when AI was involved, right at the point of creation. Waiting until it hits the internet is already too late.
Some people argue that we should just train audiences to spot fakes themselves. Don’t you think media literacy is enough?
Media literacy is crucial, but it’s not a magic shield. Humans are wired to trust sharp visuals and confident text, especially when it looks like it’s from a source we recognise. Even experts can be fooled. And here’s where it gets interesting: labels don’t just inform, they also shape perception. In user studies, content marked as AI-generated is often shared less, but sometimes it’s trusted more if the audience believes the AI is objective. That’s why developers need to think not just about technical accuracy, but also about how labels influence human behaviour over time.
What makes implementing these truth markers difficult?
Two main challenges: persistence and trust. Persistence means the label survives compression, cropping, screenshots and even frame-skipping in videos. Trust means the label can’t be forged easily. And there’s a bigger social challenge: what a trustworthy label looks like in one country may feel intrusive or biased in another. A system built for North America might not be accepted in Southeast Asia or West Africa without adaptation. Developers need to factor in these cultural dynamics early, or risk building tools that don’t get used.
How might malicious actors adapt once these systems are in place?
They will innovate. If you add watermarks, they will build tools to strip them. If you embed metadata, they will reprocess files to wipe it. One likely evolution is label mimicry, fakes that carry forged verified tags to give themselves credibility. That’s why we can’t treat labelling as a one-time fix. The technical guardrails must be part of a continually updated security layer, with rapid iteration based on emerging attack patterns.
If you were advising a generative AI team today, what would you tell them to prioritise?
Three things: dual-layer provenance. Every AI output should have a visible label for users and an invisible, cryptographically signed metadata tag for machines. If one layer fails, the other still signals origin.
Adversary testing. Simulate the ways your system could be attacked, stripping metadata, altering watermarks, and re-encoding. Fix weaknesses before release.
Cultural adaptability. Build the core technology in a way that allows different regions or platforms to customise labels without breaking the verification chain. What works visually in Lagos might not resonate in Tokyo or São Paulo.
That’s a lot of responsibility for developers. How do you balance complexity with adoption?
Start simple, but design for scale. For example, you could start by embedding robust metadata in every image and offering a public verification API. Later, you can add visible labels, regional customisation, and redundancy. The point is to make adoption easy for others, so your system can plug into a wider global network.
You talked about AI model developers changing their methods. Can you elaborate?
Treat provenance like you treat security, as a core feature, not a bolt-on. Document your approach, be transparent about its limits, and update it as threats evolve.
Remember that technology alone can’t solve disinformation; it’s also about building public trust. A good labeling system doesn’t just protect the truth; it makes the truth easier to see, no matter where in the world it travels.
As synthetic media becomes a fixture of online life, the fight against disinformation will increasingly be shaped not by politicians or platforms, but by the design choices of AI developers. Those who build with persistence, adaptability, and cultural trust in mind won’t just protect their models from misuse; they will help safeguard the integrity of public discourse in the digital age.
Disclaimer
Comments expressed here do not reflect the opinions of Vanguard newspapers or any employee thereof.